AGIBOT releases WITA-Omni embodied multimodal robot interaction model
Chinese robot maker AGIBOT releases WITA-Omni, an end-to-end embodied omni-modal interaction model trained on robot proprioceptive data. The model supports audio and video inputs and outputs, adds tactile and proprioceptive state inputs, and outputs robot actions and facial expressions, according to the company. Built on a streaming full-duplex architecture, it can listen, think, respond, move and make facial expressions simultaneously, with response latency as fast as about 400 milliseconds and averaging about 600 milliseconds — nearly three times faster than the industry average, AGIBOT said. Its omni-modal rejection capability eliminates the need for wake words by combining conversational orientation, video, audio, voiceprint, lip movement, posture, semantics and context to decide whether a current utterance needs a response, reducing false triggers...
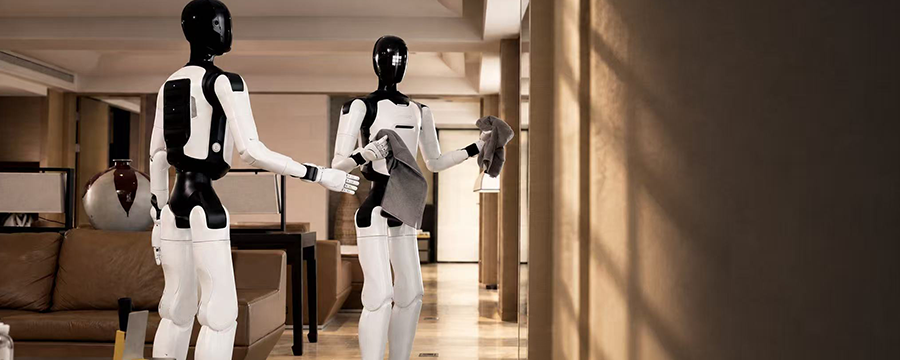 AGIBOT
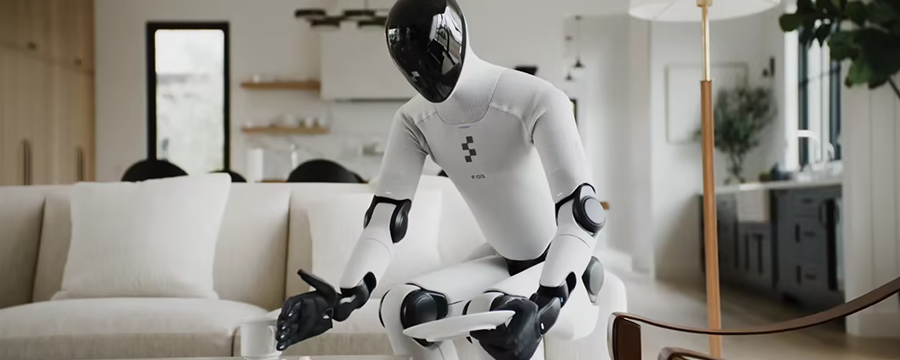 Figure AI
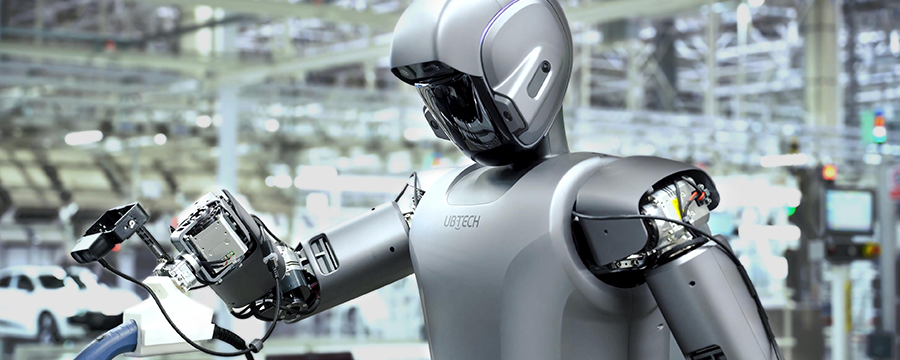 UBTECH